Category: Python

  • The Most Populated Circle on Earth (r = 20km)

    I love Tom Forth’s Population around a point website and have spent quite a bit of time there. I have often tried to find the most populated circle in certain countries but, obviously, it’s a crude way to go about it. That got me thinking, could I use convolution and NumPy to find the 20km r circle with the highest population on earth.


    Most populated r - 20km circle on earth
    Most populated r – 20km circle on earth


    Convolution slides a window over the raster and sums up what’s underneath it. Doing that pixel-by-pixel for a disc shape would be quite  slow, since it would be re-summing ~1,257 pixels at every single location on Earth. The workaround is to build the disc out of horizontal strips (each row of the circle has a width you can work out from basic circle geometry, and you sum each strip using a running cumulative sum instead of re-adding pixels every time). Stack the strips back together and you’ve got the exact disc sum, just much faster.

    I used the 2025 1km resolution Global Human Settlement Layer (GHSL) for the calculation and even on my M1 Mac, it only took about 2 minutes to run for the entire planet.

    The point that’s the centre of the r = 20km circle is here.


    One very important caveat is that there are limitations with how the dataset was created. The GHSL is not a direct headcount. It takes population totals and distributes them onto a (in this case) 1km population grid based on built-up areas. It’s essentially a (hopefully reasonably) accurate estimate.
  • Irish Census 2016 & Privacy

    I’ve been looking at the 2016 census results with the last few years and there is a great deal of suppression of values for relevant Small Areas. The CSO suppress results or aggregate them depending on the number of people living in a Small Area. If the population is too small and could lead to individuals being identified, the data is suppressed. They are legally required to undertake this exercise under s33 of the Statistics Act, 1993.

    I’ve been looking at a selection of variables and after reading this piece on the traveller accommodation crisis by RTÉ I decided to map the percentage travellers per Small Area. I have all this data in a PostGIS database but I’ll quickly run through how to do it without having to use PostGIS. I downloaded the Small Areas shapefile (generalised to 50m) and the CSV of all of the Small Area values from the CSO here. Instead of having to use a spreadsheet or QGIS to manually delete the 802 fields I didn’t need I used the pandas library, the python code below that took 0.3 seconds to run. It opens the relevant CSV and only selects the columns that I need and then strips the first 7 characters from the ‘GEOGID’ string as these are not needed for the join I’ll do in QGIS later.

    import pandas as pd, time
    
    start = time.time()
    df = pd.read_csv('SAPS2016_SA2017.csv', usecols=['GUID', 'GEOGID', 'GEOGDESC', 'T1_1AGETT','T2_2WIT'])
    
    df.GEOGID.apply(str)
    
    df['GEOGID'] = df['GEOGID'].str[7:]
    
    df.to_csv('SAPS2016_SA2017_New_GEOGID.csv')
    end = time.time()
    print(end - start)

    I then opened the shapefile in QGIS, imported the CSV and joined them. This was  subsequently exported to a GeoPackage and I used GDAL’s ogr2ogr library to convert it to a GeoJSON in order to upload it to Carto.

    ogr2ogr command to convert to GeoJSON
    ogr2ogr command to convert to GeoJSON

    Below is the resultant map with some formatting of headings undertaken to make it more legible. You can make it full screen using the button on the left. What struck me about this was how with a small amount of work it was very easy to visualise accurately the resident locations of one of the most vulnerable groups of society. Obviously this information is useful to local governments, state government agencies, NGOs and so forth but I question whether this data should been available to the general public regardless of it being aggregated to the Small Area geography.


  • ArcPY Data Driven Pages Script

    I had a situation at work a few weeks back where an individual needed 180 maps within a few hours. The maps themselves weren’t overly complex, they required satellite imagery as the basemap, some Ordnance Survey mapping overlaid with each map showcasing a particular site (in the Greater London area). I knew I wouldn’t be able to turn these around if I had to export them manually so enter ArcPy and the power of data driven pages in ArcMap.

    I used the basic ‘Grid Index Features‘ tool to create the index for the mapbook and I then created the mapbook as normal. I needed each page to only show one site, to achieve this there is a little workaround in ArcMap to white-out irrelevant features.

    The next step was to insert dynamic text for each page using a value from the attribute table (this was the layer name). I carried out a spatial join between the polygons (which contained the field with the polygon/page name) and the grid index features so that each grid index polygon would have the page/polygon name as an attribute. I then used this guidance to ensure each page had its own page number.

    Although, it would have been possible to export the mapbook from the ‘File’ menu, it would just export one (quite large) pdf with a single filename as opposed to 180 individual PDFs with each having the correct label and title. I then wrote the following python function in order to export each page. If the same file name is exported more than once it appends an underscore and number to the end. It then took about 20 minutes to export the 180 plans, automation for the win!

    #Export Data Driven Pages to PDF (Proper Names)
    import arcpy, os
    def export_pdf_maps():
    	strOutpath = r"\\Output_Location"
    	mxd = arcpy.mapping.MapDocument(r"\\Example.mxd")
    	ucodes = {}
    	for pageNum in range(1, mxd.dataDrivenPages.pageCount + 1):
    		mxd.dataDrivenPages.currentPageID = pageNum
    		pageorder = mxd.dataDrivenPages.pageRow.U_Code
    		#Check if we have already found this Ucode
    		if pageorder not in ucodes:
    			ucodes[pageorder] = 0
    		ucodes[pageorder] += 1
    		pdfname = pageorder + "_" + str(ucodes[pageorder]) + ".pdf"
    		print(pdfname)
    		if os.path.exists(strOutpath + pdfname):
    			print("Error", pdfname)		    
    		arcpy.mapping.ExportToPDF(mxd, strOutpath  + pdfname)
    	del mxd
  • Python-Quick Graph

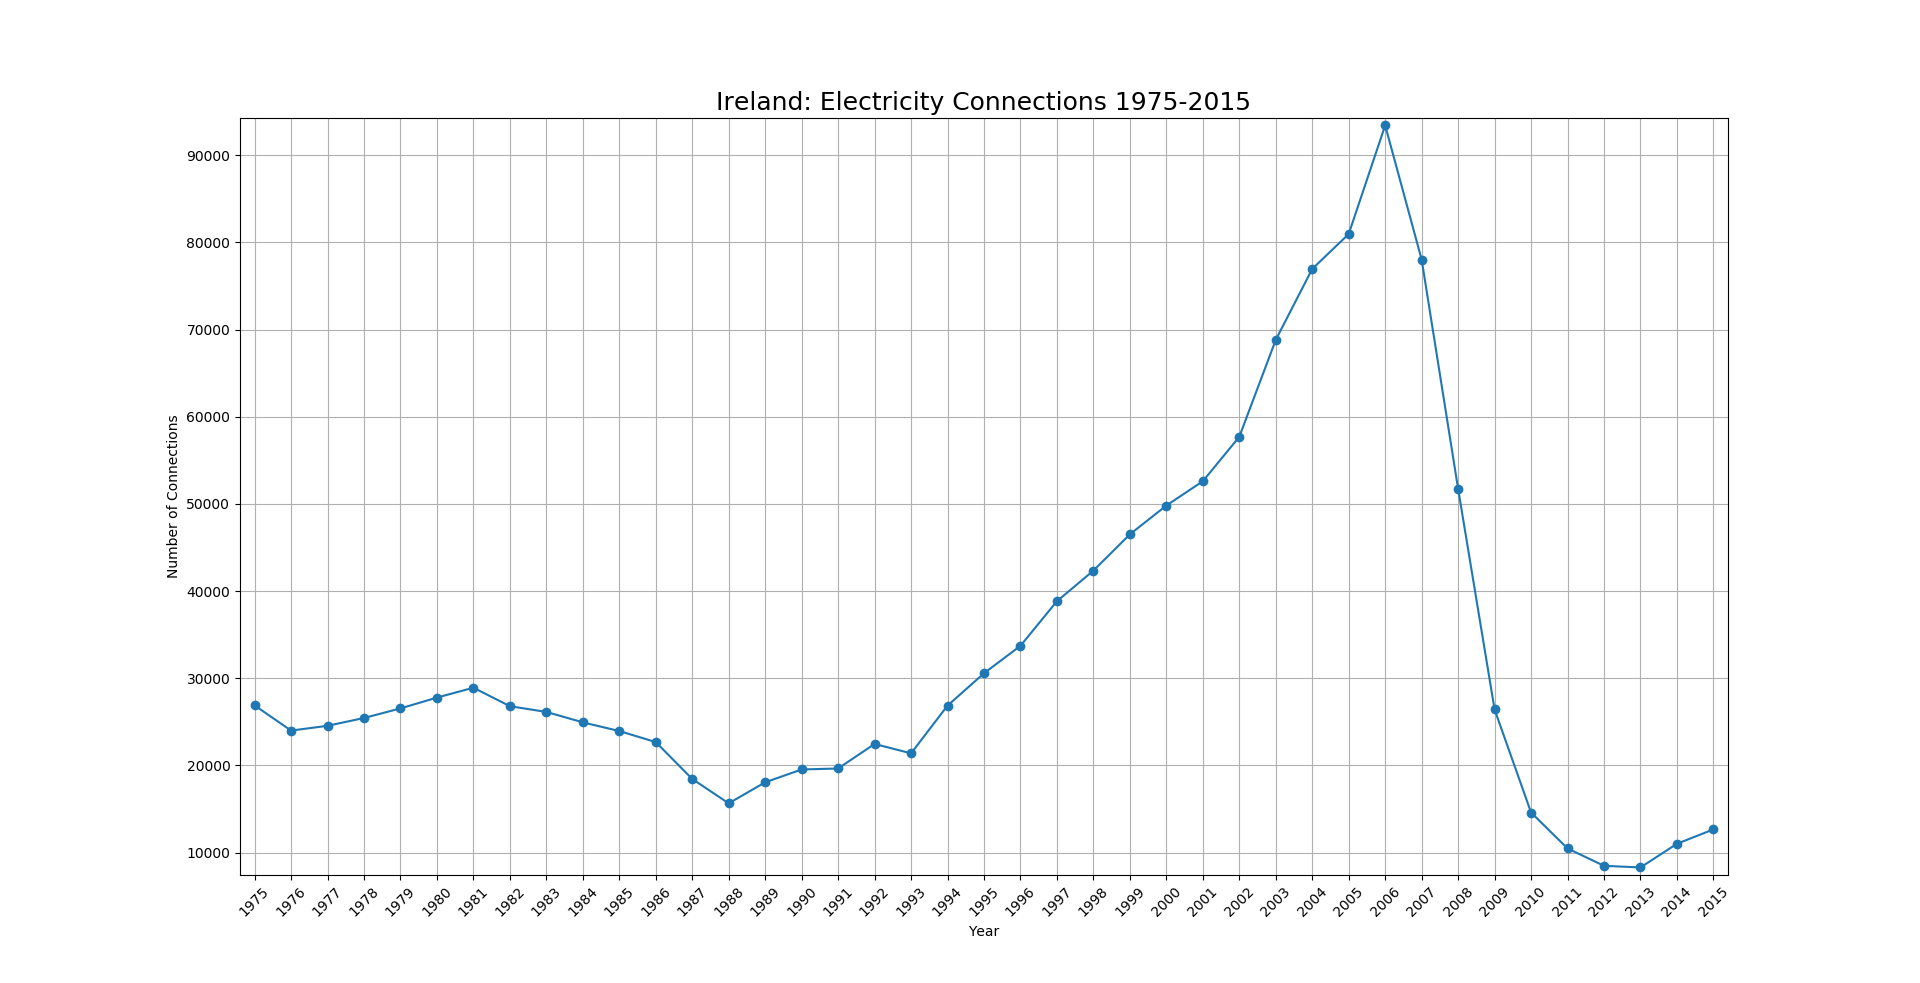
    I’ve never really had cause to use Matplotlib before so over the weekend I took a quick look at it and how useful it actually is for creating quick graphs. I took the electricity connections dataset (used as a measure of new homes built, however rough) and created a simple line graph. Below is the code I used and the result.

    import matplotlib.pyplot as plt
    
    years1 = ['1975', '1976', '1977', '1978', '1979', '1980', '1981', '1982', '1983', '1984', '1985', '1986', '1987', '1988',
    '1989', '1990', '1991', '1992', '1993', '1994', '1995', '1996', '1997', '1998', '1999', '2000', '2001', '2002',
    '2003', '2004', '2005', '2006', '2007', '2008', '2009', '2010', '2011', '2012', '2013', '2014', '2015']
    
    scores1 = [26892, 24000, 24548, 25444, 26544, 27785, 28917, 26798, 26138, 24944, 23948, 22680, 18450, 15654, 18068, 19539,
    19652, 22464, 21391, 26863, 30575, 33725, 38842, 42349, 46512, 49812, 52602, 57695, 68819, 76954, 80957, 93419, 78027,
    51724, 26420, 14602, 10480, 8488, 8301, 11016, 12666]
    
    
    fig, ax = plt.subplots()
    ax.plot(years1, scores1, marker='o')
    ax.set(xlabel='Year', ylabel='Number of Connections')
    plt.title("Ireland: Electricity Connections 1975-2015", fontsize=18)
    ax.grid()
    plt.xticks(years1, rotation=45)
    plt.margins(0.01)
    plt.show()

    And here is the resulting graph:

    Python Plot, Electricity Connections
    ESB Connections-Ireland

    The main strength I’ve seen from it is that it is very easily customisable as well as being a nice addition at various stages of a complex python script in order to error check a methodology in train.